
Good Morning!
OpenRouter text-model traffic slipped 1.8% day over day to 30.78T tokens on Nov 12, and the top three held their order: DeepSeek V4.1 Flash at 11.74T, Hy4 at 2.74T, GLM 5.3 Flash at 1.64T.
The moves sat underneath. GLM 5.3 Flash fell 37.0%, Claude Opus 5.5 rose 13.4%, and GPT-6.1 Sol climbed from ninth to seventh on 12.1% growth.
Model | tokens | DoD (11/11) | |
1 | DeepSeek V4.1 Flash · DeepSeek | 11.74T | – -2% |
2 | Hy4 · Tencent | 2.74T | – +1% |
3 | GLM 5.3 Flash · Z.ai | 1.64T | – -37% |
4 | GPT-6 Luna · OpenAI | 1.35T | – +8% |
5 | Claude Opus 5.5 · Anthropic | 1.18T | – +13% |
6 | DeepSeek V4 Flash · DeepSeek | 0.84T | – -14% |
7 | GPT-6.1 Sol · OpenAI | 0.73T | ▲2 +12% |
8 | MiMo-V2.6-Flash · Xiaomi | 0.64T | – -5% |
9 | GLM 5.3 · Z.ai | 0.61T | ▼2 -23% |
10 | Nemotron 3.5 Super VL · NVIDIA | 0.58T | – +9% |
Gemini 4 Hydrogen Costs $1.50/M
TL;DR: Google released Gemini 4 Hydrogen in AI Studio and the Gemini API, including the free tier. Paid rates are $1.50 per million input tokens and $7.50 per million output tokens across its 1 million token context window. On Artificial Analysis’s Intelligence Index, it scores 51 at its default high reasoning setting and 54 at its highest setting. Read more →
Seedance 2.5 Flash Cuts Video Costs
TL;DR: ByteDance says Seedance 2.5 Flash generates 720p video from text or images at nearly twice the speed of Seedance 2.5 and costs about 34% less, at $0.152 per output second on BytePlus. ModelArk API access is scheduled for Nov. 15 at 2 p.m. China time. Read more →
Inkling 2 Small Opens Weights
TL;DR: Thinking Machines Lab released downloadable Inkling 2 Small weights under Apache 2.0 after debuting the model on Tinker last week. The mixture-of-experts model has 594 billion parameters, with 17 billion active per token. It accepts text and images and lets developers adjust how much reasoning it does. Read more →
Muse Spark Open Hits 1,109 Tokens/s
TL;DR: LMSYS raised Muse Spark Open’s decoding speed from 517 to 1,109 tokens per second on eight Nvidia GB300 GPUs in a single-request GSM8K test. Its SGLang megakernel cut GPU kernel launches per decode step from about 1,450 to 97. The implementation currently supports one request at a time with speculative decoding. Read more →
Intel Details a 480GB GPU Option
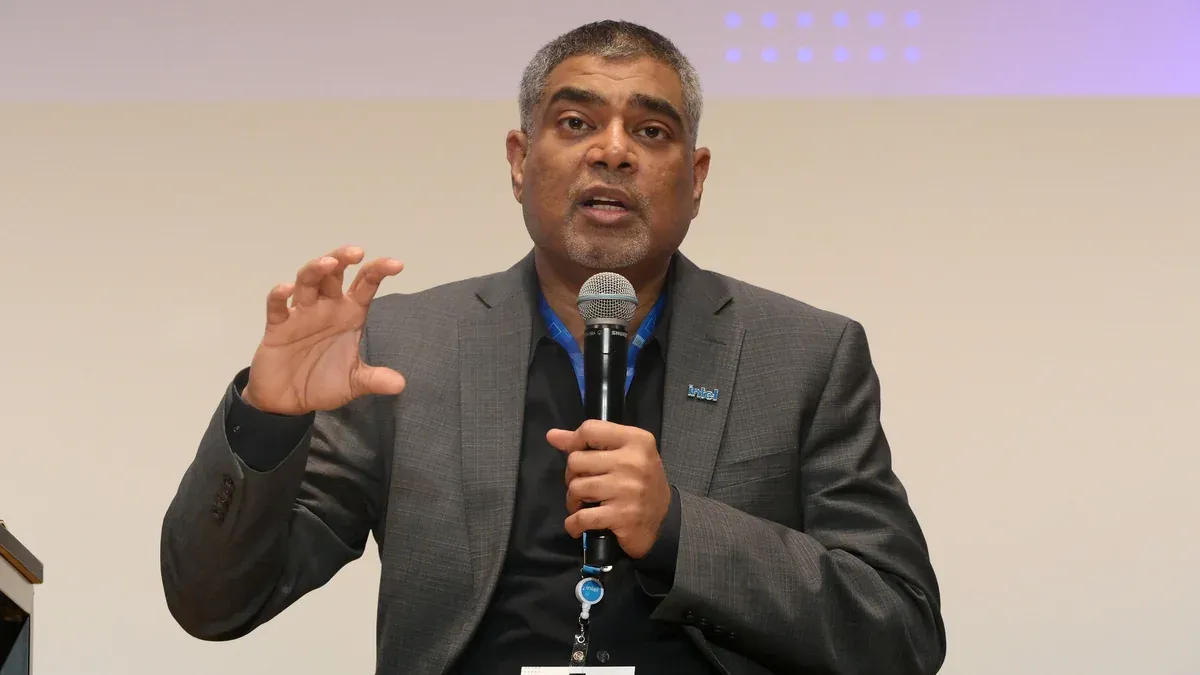
TL;DR: Intel says server makers will be able to buy its Crescent Island inference GPU as a standalone chip and design boards with up to 480GB of memory. Intel’s own card has 160GB. The company says it is shipping evaluation samples to customers. Read more →
Perplexity Decider 1.3 Adds Text Extraction
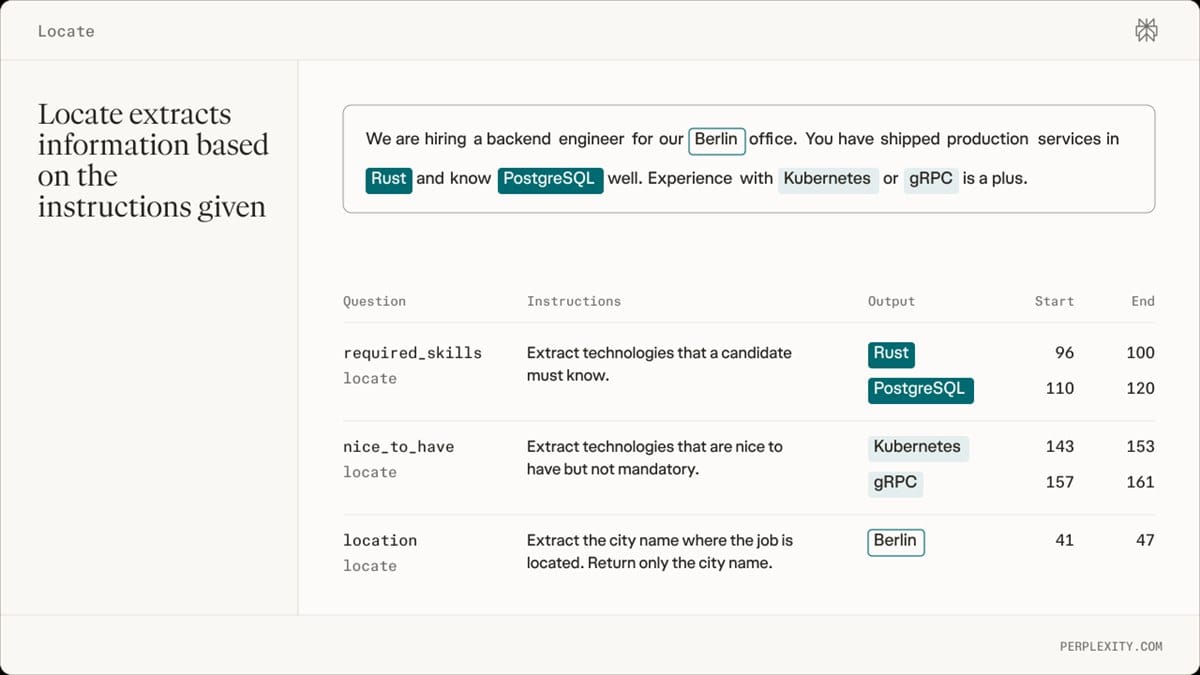
TL;DR: Perplexity released Decider v1.3 and Decider Flash v1.3 with downloadable weights under Apache 2.0. Both add Locate, which extracts matching text and returns its start and end positions. A single request can classify a job listing and pull out the skills it requires. Read more →
Runway Opens Praxis-1 Weights
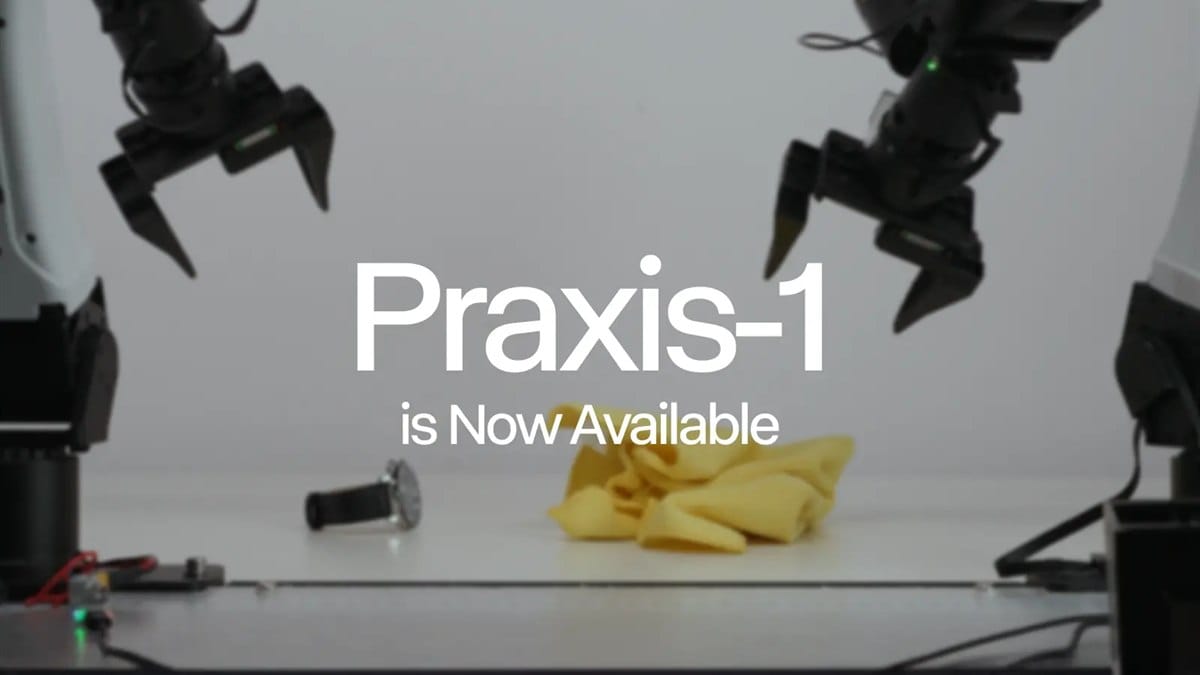
TL;DR: Runway released weights and fine-tuning code for Praxis-1 under Apache 2.0. The 27B model predicts video and robot actions together. Runway reports a 46.2% success rate across 1,200 simulated episodes on NVIDIA’s RoboLab-120 benchmark. Read more →
Top AI models. Lower costs.
Access GPT, Claude, Gemini, and more through one OpenAI-compatible API—and save up to 70% on AI API costs. Create your DIT account, get your API key, and start building.