
Good Morning!
Tencent's Hy4 and Kimi K3 forced their way into the leaders while the whole board shrank slightly, Hy4 arriving from nowhere onto the podium and Kimi climbing from nineteenth to eighth. Kimi grew both ways, more calls and heavier jobs. Hy4 is the opposite of a crowd, relatively few calls carrying about 140,000 tokens each, while GPT-6.1 Sol piled up many smaller code jobs. GLM 5.3 Flash and MiniMax M3.1 Flash leaked the same way, fewer calls and lighter jobs, with GLM shedding about a third of its volume. Kimi and Sol added calls; the fallers lost them.
Model | tokens · vs. previous day (Nov 3) | ||
1 | DeepSeek V4.1 Flash · DeepSeek | 13.19T | – -0% |
2 | GLM 5.3 Flash · Z.ai | 1.92T | – -35% |
3 | Hy4 · Tencent | 1.29T | NEW |
4 | Claude Opus 5.5 · Anthropic | 1.15T | ▲1 +5% |
5 | GPT-6 Luna · OpenAI | 1.14T | ▼1 +1% |
6 | DeepSeek V4 Flash · DeepSeek | 0.88T | – -2% |
7 | MiniMax M3.1 Flash · MiniMax | 0.74T | – -16% |
8 | Kimi K3 · MoonshotAI | 0.67T | ▲11 +92% |
9 | Nemotron 3.5 Super VL · NVIDIA | 0.62T | – +21% |
10 | GPT-6.1 Sol · OpenAI | 0.59T | – +17% |
GPT Image 2.6 Launches
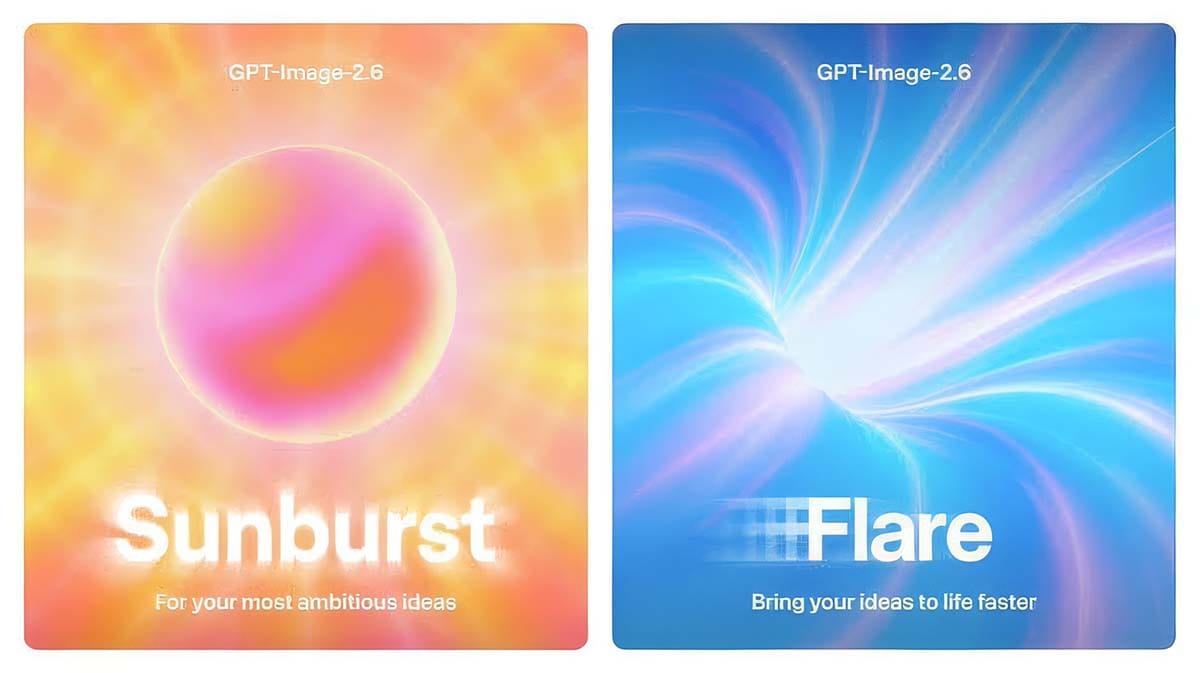
TL;DR: OpenAI launched Images 2.6 across ChatGPT, Codex, and the API, claiming 50% faster image generation. The update adds GIF creation, reusable reference images, and improved consistency across edits. Developers get two API models: Flare for speed, generating images in as little as six seconds, and Sunburst for higher-quality, more consistent edits. New API features include image markup for precise local changes and SVG exports for scalable graphics. Read more →
Moonshot Releases Kimi K3.1 Pro Weights
TL;DR: Moonshot AI published the weights for Kimi K3.1 Pro, a mixture-of-experts model with 2.8 trillion total parameters and 104 billion active parameters. The checkpoint is about 1.56 TB on Hugging Face and is available under Moonshot’s custom model license. Read more →
Tencent Adds Vision to Hy4
TL;DR: Tencent released the full version of Hy4 after its August preview. The new version adds visual understanding for tasks such as interpreting complex charts and solving math problems that include images. Tencent is also using Hy4 to power an update to its WorkBuddy AI assistant. Read more →
Oracle Reportedly Drops $7B Tencent Chip Lease
TL;DR: Oracle canceled a five-year deal to lease advanced AI chips to Tencent after pressure from the Trump administration, the Financial Times reported. The agreement was valued at about $7 billion and would have given Tencent access to as many as 100,000 chips in Oracle data centers in Southeast Asia. Read more →
Ripple-65B Scores 80.5 on Terminal-Bench
TL;DR: Ricursive Intelligence released Ripple-65B Preview, a dense model pretrained from scratch on 12 trillion tokens. It scored 80.5 on Terminal-Bench 2.1 in the developer’s tests, ahead of several larger open-weight models in that comparison. Read more →
Cognition Launches SWE-2 Flash
TL;DR: Cognition introduced SWE-2 Flash, a coding model based on Thinking Machines’ Inkling-Small. In Cognition’s tests it beat the U.S. open-weight models in its comparison on selected coding evaluations. Cognition is developing a program to share the weights with partners and researchers. Read more →
Sarvam Releases Prism for Fast Decisions
TL;DR: Sarvam AI released Prism for tasks with a fixed set of choices, such as routing support requests. The model returns a probability for each option. Sarvam measured a median response time of 44 ms on one NVIDIA B200. Prism is available via API and as Apache 2.0 weights. Read more →
Together AI Recompiles Inference as Traffic Shifts
TL;DR: Together AI introduced a compiler that uses agents to optimize its inference stack as models and traffic patterns change. The research team says it could run 252 times as many optimization experiments per hour as prior agent-based systems. It says the compiler already serves production traffic. Read more →
llama.cpp Adds FP8 and Faster Cache
TL;DR: llama.cpp 0.9.0 adds OCP FP8 E4M3 quantization and an attention operation designed to make its unified KV cache more efficient when serving multiple sequences. The release also adds support for four model architectures, including Mistral Large 4. Read more →
Unsloth Updates Qwen Flash-Next Quants
TL;DR: Unsloth released Dynamic V3.1 GGUFs for Qwen3.8-Flash-Next. Its tests compare how much of the baseline model’s accuracy each quant retains on tasks including Terminal-Bench 2.1 and DeepSWE v1.1, with agent benchmarks run at 256K context. The release also lets users swap in higher-precision engram tables. Read more →
Top AI models. Lower costs.
Access GPT, Claude, Gemini, and more through one OpenAI-compatible API—and save up to 70% on AI API costs. Create your DIT account, get your API key, and start building.