
Good Morning!
OpenRouter text-model traffic reached 27.84T tokens on Nov 9, down 3.0% on the Monday before, and the top of the board moved far more than the total did.
Tencent's Hy4 doubled to 3.18T and took second place; GLM 5.3 Flash lost 41.7% to 1.51T and gave that place up.
Model | tokens | WoW (11/2) | |
1 | DeepSeek V4.1 Flash · DeepSeek | 9.53T | – -7% |
2 | Hy4 · Tencent | 3.18T | ▲1 +101% |
3 | GLM 5.3 Flash · Z.ai | 1.51T | ▼1 -42% |
4 | GPT-6 Luna · OpenAI | 1.02T | ▲1 -10% |
5 | Claude Opus 5.5 · Anthropic | 0.95T | ▲1 -3% |
6 | DeepSeek V4 Flash · DeepSeek | 0.84T | ▲1 -9% |
7 | crouton-alpha · stealth | 0.83T | NEW |
8 | Kimi K3.1 Pro · MoonshotAI | 0.74T | ▲1 +3% |
9 | MiMo-V2.6-Flash · Xiaomi | 0.66T | ▲7 +83% |
10 | MiniMax M3.1 Flash · MiniMax | 0.56T | ▼2 -38% |
Meta Launches Muse Ember
TL;DR: Meta launched Muse Ember for repeated agent tasks such as tool calls, routing, extraction and code fixes. The model accepts text, images, audio and video, with a one-million-token context window. Meta Model API pricing is $0.10 per million input tokens and $0.50 per million output tokens, with cached input priced at $0.004 per million tokens. Read more →
Meituan Opens LongCat 2.5
TL;DR: Meituan released LongCat-2.5’s weights under the MIT license. The multimodal mixture-of-experts model has 1.6 trillion total parameters, with about 48 billion active per token, and combines visual understanding with multi-step coding. It can work from screenshots and handle codebase tasks; the release includes deployment guidance for running the model on domestic AI accelerators. Read more →
Nemotron 3.5 Lands on SageMaker
TL;DR: Nvidia’s Nemotron 3.5 Super VL is now available through Amazon SageMaker JumpStart, adding a managed deployment path for the existing open model. The 120B-parameter vision-language model activates 12B parameters per token and supports up to one million context tokens. JumpStart offers NVFP4 and BF16 variants for document analysis, computer-use agents and video question answering. Read more →
Google Doubles TPU Bandwidth
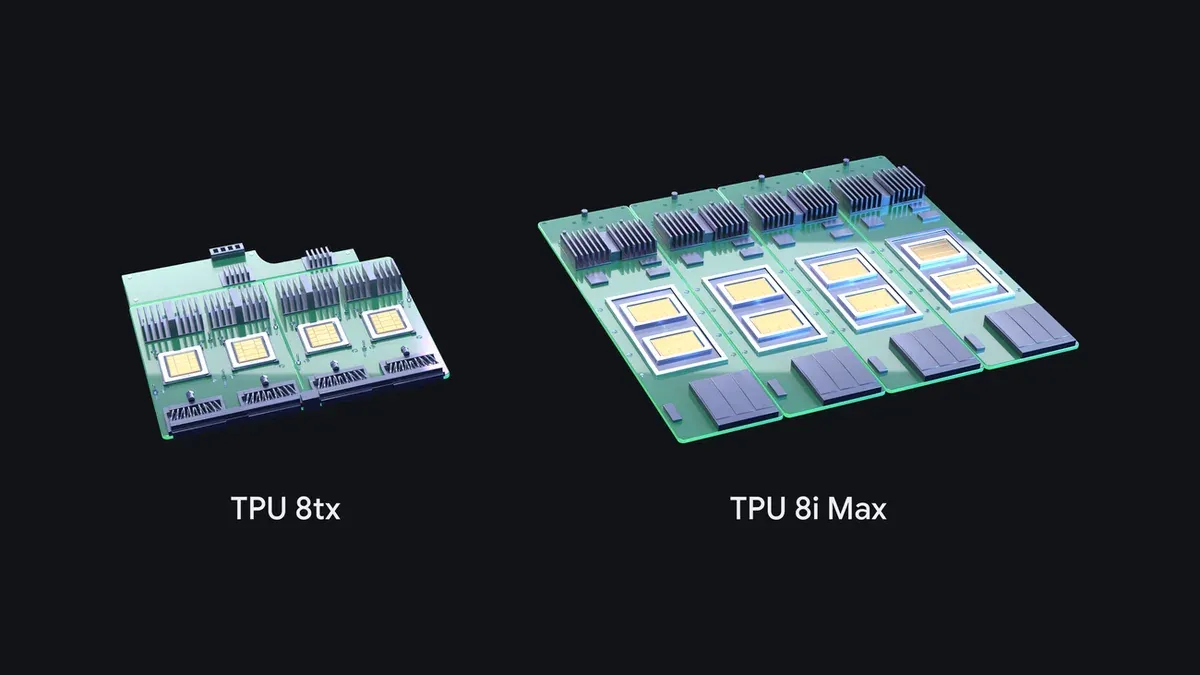
TL;DR: Google added two systems to its eighth-generation TPU lineup. TPU 8i Max packages two TPU 8i chips together, doubling compute, on-chip SRAM and high-bandwidth memory bandwidth compared with TPU 8i. TPU 8tx pairs TPU 8t silicon with AMD EPYC hosts, adding hardware protection and isolation for sensitive data and model weights during inference and private fine-tuning. Read more →
Top AI models. Lower costs.
Access GPT, Claude, Gemini, and more through one OpenAI-compatible API—and save up to 70% on AI API costs. Create your DIT account, get your API key, and start building.