
Good Morning!
MiniMax M3.1 Flash rose 24.5% to seventh on Oct 27 and fits in 143.9GB: with half our top 10 Flash-tier, cheap models are becoming the default, even locally.
Model | tokens · vs. previous day (Oct 26) | ||
1 | DeepSeek V4.1 Flash · DeepSeek | 8.40T | – +10% |
2 | GLM 5.3 Flash · Z.ai | 1.88T | – -18% |
3 | Hy4 preview · Tencent | 1.35T | ▲1 -3% |
4 | GPT-6 Luna · OpenAI | 1.11T | ▼1 -29% |
5 | DeepSeek V4 Flash · DeepSeek | 1.10T | ▲1 +7% |
6 | Claude Opus 5.5 · Anthropic | 1.10T | ▼1 +6% |
7 | MiniMax M3.1 Flash · MiniMax | 0.84T | ▲1 +24% |
8 | GLM 5.3 · Z.ai | 0.71T | ▼1 -21% |
9 | MiMo-V2.6-Flash · Xiaomi | 0.52T | ▲1 +9% |
10 | Hy3 · Tencent | 0.46T | ▼1 -11% |
MiniMax M3.1 Flash Shrinks to 2-Bit
TL;DR: Unsloth's Dynamic GGUFs bring MiniMax M3.1 Flash, a 428B-parameter open-weight MoE model, down to a 143.9GB 2-bit footprint with 91.5% top-1 token agreement across seven domains. Builders can now self-host it through llama.cpp or Unsloth Desktop behind an OpenAI-compatible API, with a much lower memory barrier. Read more →
Google Unveils Genie 4 World Model
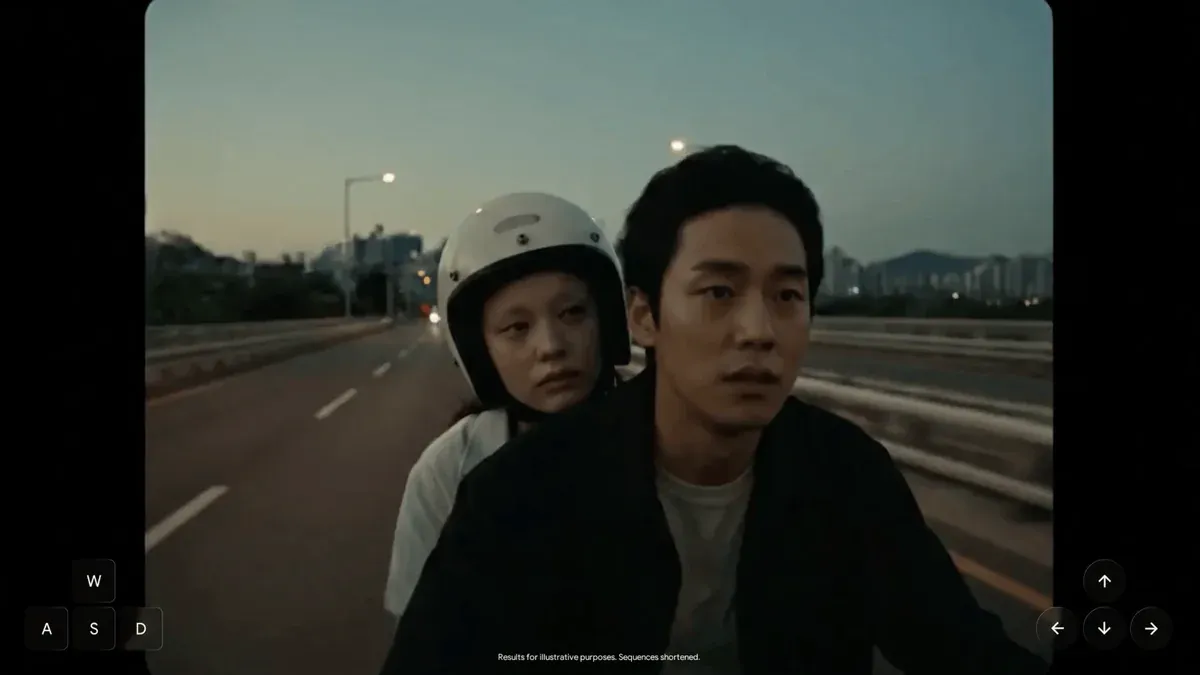
TL;DR: Google announced Genie 4, its latest world model for generating interactive experiences, now in a research preview for trusted testers. The update brings more realistic worlds, lets users change a scene in real time with a natural-language prompt, and adds generated audio. For builders, it moves world models closer to interactive, prompt-driven environments rather than one-shot video clips. Read more →
MiniCPM Open-Sources Compact OCR Models
TL;DR: The MiniCPM team released the open-source MiniCPM-OCR suite with two models. MiniCPM-OCR 1.0, at 1B parameters, scores 93.68 on Real5-OmniDocBench and 54.7 on OCRBench v2. MiniCPM-OCR Jev, a 2B model-agnostic checker for text, formulas and tables, approaches Qwen3.5-397B-A17B on JevOCRBench. Read more →
vLLM Router Ships 27B Decision Model
TL;DR: vLLM Semantic Router released d3-ultra, a 27B open-weight multimodal decision model. It reads text, images and video in a single pass and returns probabilities for every answer, scoring 87.2 on the team's SR-Text test. It gives teams an open model for classification and routing decisions across modalities. Read more →
FrontierCode 2.0 Tops Out at 45%
TL;DR: FrontierCode 2.0, a new coding benchmark, moves past spec-following and asks whether a model's pull request should be merged at all. Tasks are more diverse and larger in scope, with deliberately underspecified prompts that test engineering judgment. The top model scores just 45%, leaving wide headroom to separate coding models. Read more →
Rubin NVL72 Runs Kimi K3 Fast
TL;DR: NVIDIA's Rubin NVL72 reached over 850 tokens per second per user running Kimi K3, a 2.8-trillion-parameter model, in preliminary SemiAnalysis tests. Using Dynamo and vLLM, Rubin delivered roughly 2.4–3.2x more tokens per dollar than GB300 NVL72 at matched generation speeds. The results remain an early performance preview. Read more →
OpenAI's Richard Ho Discusses Jalapeño Chip
TL;DR: Tae Kim's Key Context newsletter published an interview with OpenAI's Richard Ho about Jalapeño, the custom AI chip OpenAI is developing. Custom silicon is one of the few levers a lab has over its own compute costs, so OpenAI's chip plans matter to anyone paying for its models over the long run. Read more →
Nvidia and AMD Invest in Meta
TL;DR: Nvidia and AMD plan to invest $4 billion in Meta, with Nvidia contributing $3 billion and AMD $1 billion, as part of Meta's expanded $97.5 billion equity fundraising plan. The investments tie two major chip suppliers more closely to their biggest customer, highlighting the increasingly circular flow of capital financing the AI infrastructure boom. Read more →
Top AI models. Lower costs.
Access GPT, Claude, Gemini, and more through one OpenAI-compatible API—and save up to 70% on AI API costs. Create your DIT account, get your API key, and start building.