
Good Morning!
Alibaba's new model has 2.4 trillion parameters but uses fewer tokens. Even artificial intelligence is being told to stop talking so much.
Model | tokens | WoW (11/9) | |
1 | DeepSeek V4.1 Flash · DeepSeek | 11.38T | – +19% |
2 | Hy4 flash · Tencent | 1.88T | NEW |
3 | GLM 5.3 Flash · Z.ai | 1.41T | – -6% |
4 | Claude Opus 5.5 · Anthropic | 1.33T | ▲1 +40% |
5 | GPT-6 Luna · OpenAI | 1.27T | ▼1 +25% |
6 | Hy4 · Tencent | 1.10T | ▼4 -65% |
7 | DeepSeek V4 Flash · DeepSeek | 0.64T | ▼1 -24% |
8 | MiMo-V2.6-Flash · Xiaomi | 0.59T | ▲1 -10% |
9 | Nemotron 3 Ultra · NVIDIA | 0.54T | ▲2 +1% |
10 | MiniMax M3.1 Flash · MiniMax | 0.53T | – -5% |
Qwen4-Max Goes Live
TL;DR: Alibaba launched Qwen4-Max on the QwenCloud API after an earlier preview. The flagship has 2.4 trillion parameters, handles images natively and supports a one-million-token context. On Alibaba’s Work360 test at high reasoning effort, it used 35% fewer tokens and cut average task cost by about 60% versus Qwen3.8-Max. Read more →
Liquid d1.2 Adds Audio
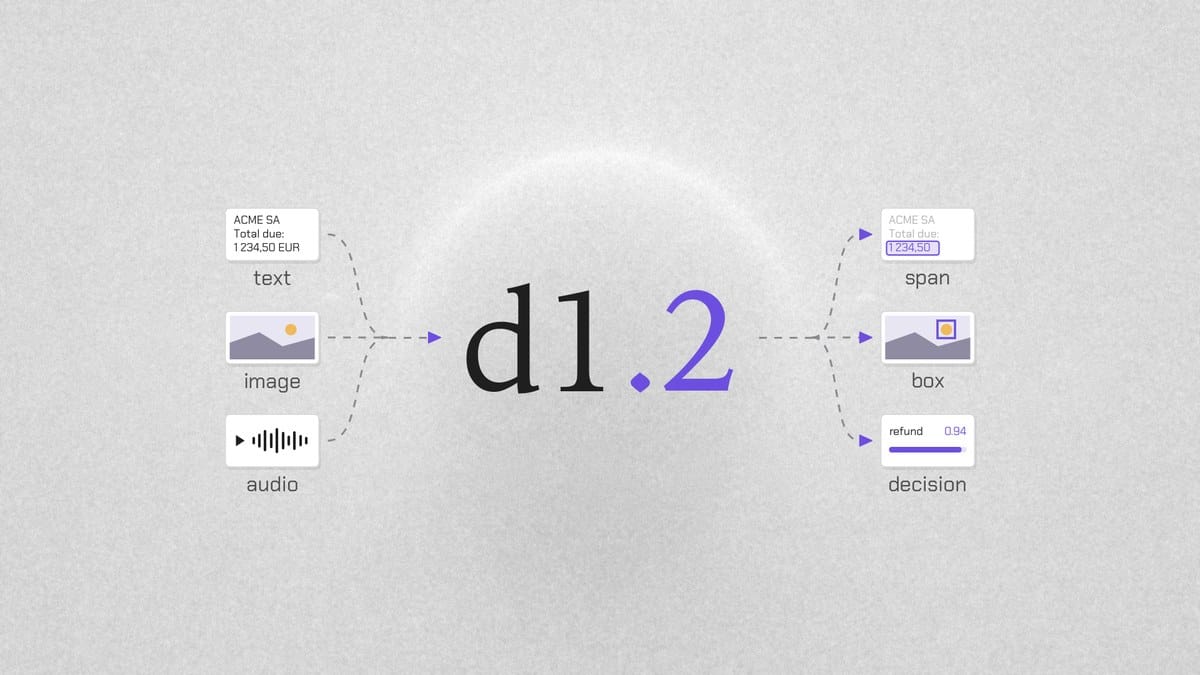
TL;DR: Liquid AI released d1.2 and d1.2-ultra with audio inputs and five new structured tasks. The models can classify audio clips or take spoken questions, and they bill only for input. Prices are $0.02 and $0.042 per million input tokens, respectively. Liquid reports a score of 75 for Ultra on the Artificial Analysis Decision Index v2.1. Read more →
Rubin HPC Hits 50K Cores
TL;DR: Nvidia unveiled Rubin HPC at SC26, a GPU designed for scientific simulation and analytics. It has more than 50,000 CUDA cores, hardware acceleration for sparse data and seventh-generation NVLink for GPU-to-GPU communication. Nvidia expects availability in 2028. Read more →
Tencent Launches Hy4 Flash
TL;DR: Tencent released Hy4 flash, a multimodal model with 224 billion total parameters, 12 billion active parameters and up to one million tokens of context. Tencent Cloud lists standard rates of $0.07 per million input tokens and $0.281 per million output tokens, with a 50% API discount through Nov. 30. Read more →
Vera Rubin Leads MLPerf Training
TL;DR: Nvidia reported up to twice the training performance per GPU on Vera Rubin NVL72 versus GB300 NVL72 in MLPerf Training v6.1. In a separate provisional MLPerf Endpoints result, Vera Rubin delivered more than 10 times GB300’s throughput per watt on Kimi K3 at the same response speed. Read more →
Sage Opens Scientific Model Weights
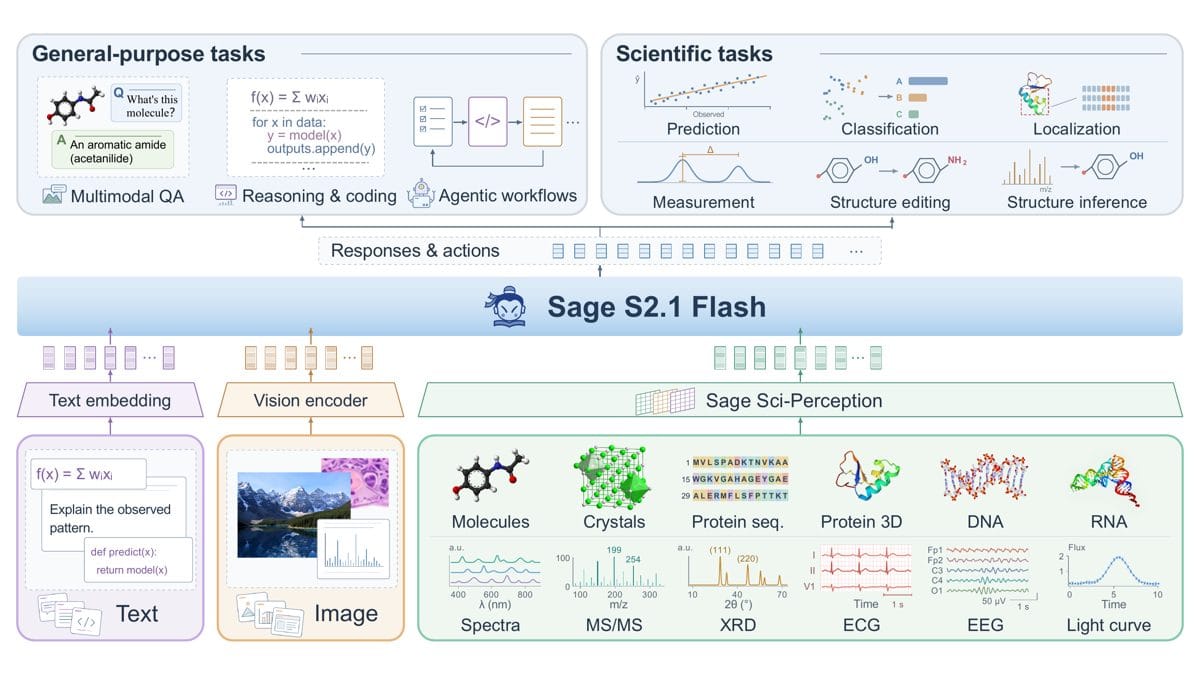
TL;DR: Shanghai AI Laboratory released Sage S2.1 Flash weights under MIT, including an FP8 version. The multimodal model can read molecular graphs, crystal structures and protein sequences, then use code and specialized tools to analyze them. It can check intermediate results and adjust its next step during multi-stage research tasks. Read more →
Together Rethinks GPU Kernel Fusion
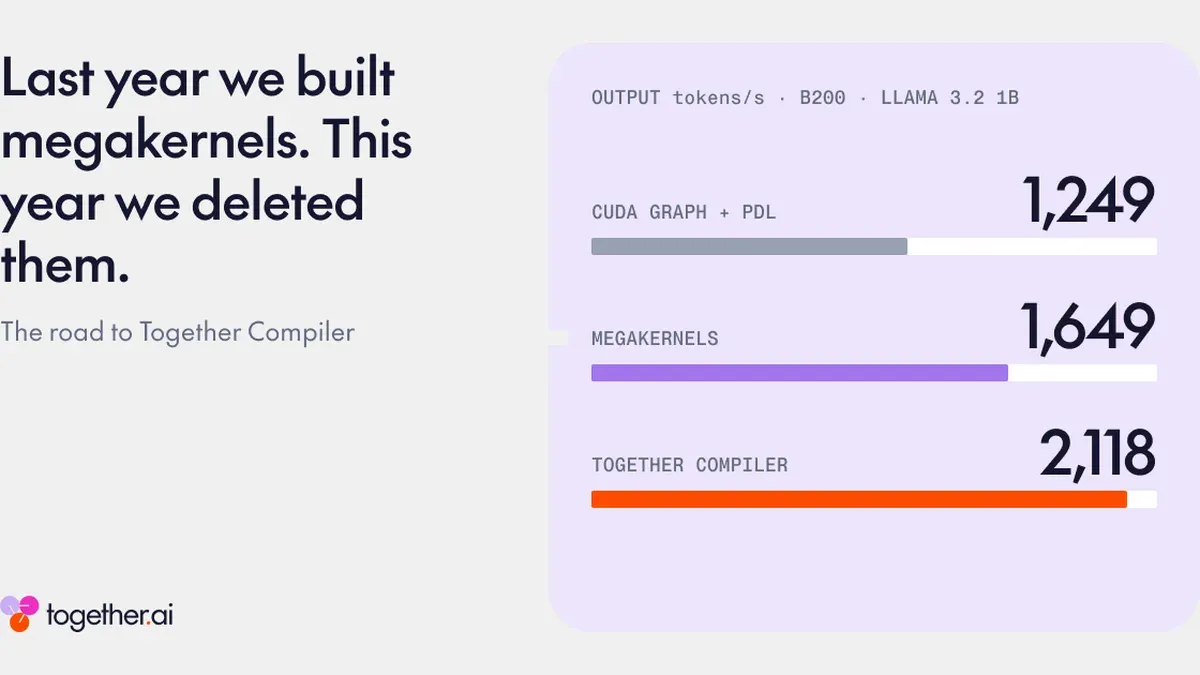
TL;DR: Together AI explained where breaking up a GPU megakernel helps. On Kimi K3 with uneven expert routing, moving expert dispatch to the GPU’s copy engine ran 6.9% faster than the Mixture of Kitten megakernel. The post also revisits its Llama 3.2 1B result, where agent-tuned kernels ran 28% faster on a B200. Read more →
Top AI models. Lower costs.
Access GPT, Claude, Gemini, and more through one OpenAI-compatible API—and save up to 70% on AI API costs. Create your DIT account, get your API key, and start building.